
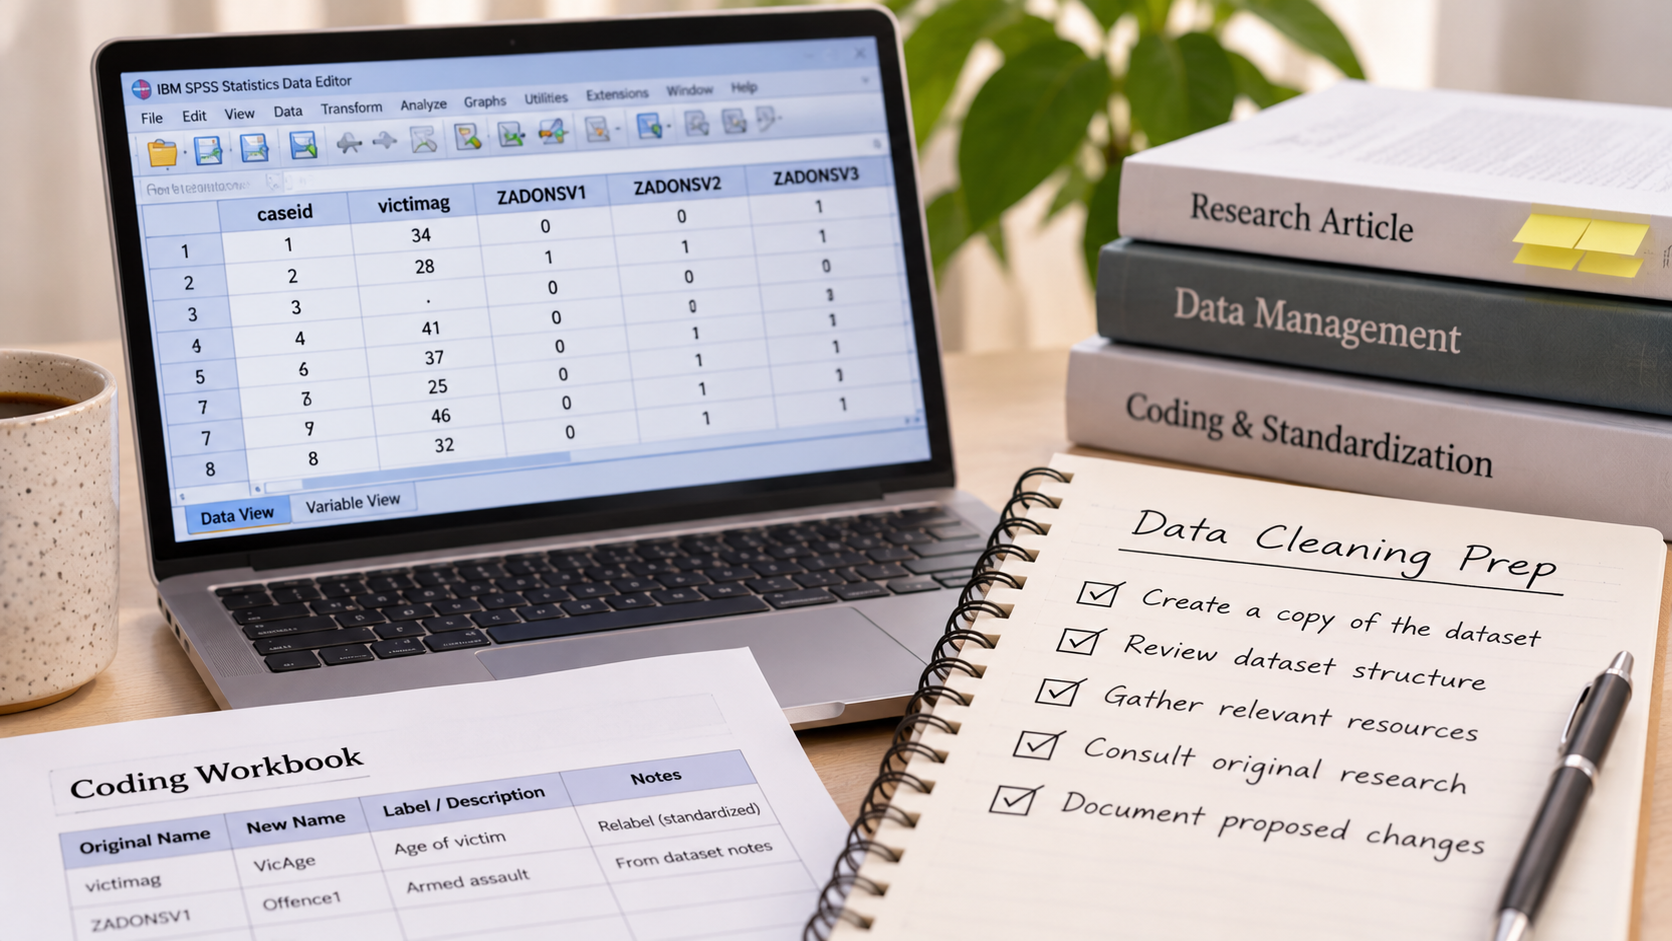
Working with an unfamiliar dataset for the first time can feel overwhelming. With countless variables, unfamiliar terminology, and information that may not immediately make sense, knowing where to begin is often one of the biggest challenges. Through their Independent Research Projects (IRPs), SAVE Lab students have gained hands-on experience navigating, reviewing, and standardizing datasets. Here, they share some of the practical lessons they have learned along the way and advice for students beginning their own data-cleaning projects.
1. Where Do You Even Start?
Data cleaning is similar to investigating a crime scene. You would not walk in and immediately start moving things around or drawing conclusions. Instead, you would first survey the scene, document what you find, and consider what the evidence might tell you. As Olyvia explains, approaching an unfamiliar dataset requires that same level of care. Before making any changes, it is important to establish what you are working with.
A good starting point is to examine the overall structure of the dataset rather than immediately focusing on individual entries. Olyvia recommends looking at the number of rows and columns, variable names and labels, missing entries, and the types of information being recorded. In her IRP, she was assigned a French-language dataset, drawing on her French proficiency to help navigate and interpret the information. She translated variable labels into English, reviewed accompanying notes, and consulted the original research publication to gain additional context.
For example, Olyvia encountered variables labelled “ZADONSV1,” “ZADONSV2,” and “ZADONSV3.” Their names offered few clues about what they represented. By consulting the accompanying notes, she was able to identify them as specific offence categories, including armed assault, murder, and unlawful confinement. Her experience highlights the importance of looking beyond variable names and using available documentation to understand what the data actually represents.
Similarly, Teagan recommends beginning in SPSS by reviewing the Overview tab to get a general understanding of the dataset. This provides information about the number of variables and cases or participants, helping researchers understand the size of the dataset and determine whether similarly named files are actually different versions of the same dataset. From there, the Variable View tab allows researchers to examine individual variable names, labels, and descriptions.
Teagan also emphasizes the value of having supporting resources available while working through a dataset. During her IRP, she kept the Data Cleaning Instruction Sheet, the Coding Workbook Spreadsheet, the Highlander Dataset, and her current dataset open simultaneously. The Highlander Dataset provided standardized variable names that helped guide her decisions when renaming variables or identifying additional variables that needed to be incorporated. For example, she used the Highlander Dataset to determine that the variable “victimag” should be relabelled as “VicAge.”
When variable names or descriptions were ambiguous, Teagan consulted syntax files, other datasets, and the original research publication to verify their meaning. These resources helped her make informed decisions rather than relying on assumptions.
Both experiences demonstrate that understanding a dataset requires more than simply looking at the data itself. Taking the time to examine its structure, consult supporting documentation, and compare it against existing resources can help establish a clearer starting point. As Olyvia reminds us, not everything will make sense right away. Encountering unclear variables or unfamiliar terminology is part of the process, not a sign that you are doing something wrong. Rather than feeling pressured to figure everything out at once, allow yourself time to investigate and ask questions along the way. Sometimes, you have to follow a few clues before the bigger picture starts to make sense.
2. Before You Start Cleaning
Once you have familiarized yourself with a dataset, it can be tempting to start making changes immediately. However, preparation is just as important as the cleaning itself.
One of the most important recommendations from both Victoria and Faith is to create a secondary copy of the dataset before making any modifications. Working from a copy protects the original data from irreversible changes and is particularly important when working with shared research data.
Victoria also cautions against assuming that a dataset labelled “original” is necessarily the most accurate or up-to-date version. During her initial experience with data cleaning, she encountered multiple datasets with similar names and initially assumed that the version labelled “original” was the most reliable. She later learned that subsequently saved versions may contain corrections or newly created variables that are important to the research. Her advice is to retain copies of seemingly duplicate datasets and compare their contents before deciding whether any version is redundant.
Another important recommendation from Victoria is to maintain a spreadsheet documenting proposed changes before implementing them. This spreadsheet should include each variable’s original name and descriptors, proposed modifications, and evidence-based justifications for each decision. Consulting existing precedents wherever possible can also help researchers identify established variable names and descriptions that accurately reflect the constructs being measured.
Faith highlights another important aspect of preparation: understanding the research instruments and background knowledge relevant to the dataset. Before beginning her data-cleaning work, she familiarized herself with questions from various static sexual recidivism risk assessments, paying particular attention to the STATIC-99R and the age variable from the STATIC-99. Understanding these assessments helped her identify potential assessment-related questions within her dataset.
Faith also recommends becoming comfortable with SPSS before attempting to interpret or standardize variables. To organize her initial findings, she created a document recording key information about the dataset, including its sample size, language, and number and order of variables. She continued updating this document as she learned more about the data.
When she encountered unfamiliar variables, Faith consulted the original research publication associated with her dataset, known as the Proulx dataset. By searching for research related to Jean Proulx and sexual recidivism, she located relevant publications and compared their reported sample sizes with the dataset she was examining. Once she identified a publication with a matching sample size, she used it as a reference to guide her investigation and standardization of the dataset.
Together, these experiences highlight the importance of gathering the right resources before making changes. Whether it is an original research publication, assessment instrument, coding workbook, data-cleaning instruction sheet, syntax file, or previously standardized dataset, each resource can provide valuable context for interpreting variables and supporting informed decisions.
Ultimately, data cleaning is not a process that should be undertaken hastily. As Victoria emphasizes, it requires a considerable commitment of time, supplementary research, and attention to detail. Taking the time to understand the dataset, preserve original files, consult established resources, and document decisions can help researchers approach the process more confidently and consistently.
A Final Takeaway
Whether you are opening an unfamiliar dataset for the first time or preparing to standardize its variables, the most important thing is to take your time. Start by understanding what you have, investigate anything that is unclear, and let the available evidence guide your decisions. As our SAVE Lab students demonstrate, a thoughtful and well-documented approach to data cleaning is essential to producing accurate, consistent, and reliable research data.
Insights and reflections contributed by Olyvia Williams, Teagan Fraser, Victoria Garisto, and Faith Hadcock, SAVE Lab Independent Research Project students.
Leave a Reply